Voice AI. Built to be owned.
The complete voice AI stack, from speech models to orchestration, deployed on your infrastructure in India, US & UK, with your data, your model and your economics.
Our clients & pilots
We're part of
National Recognition
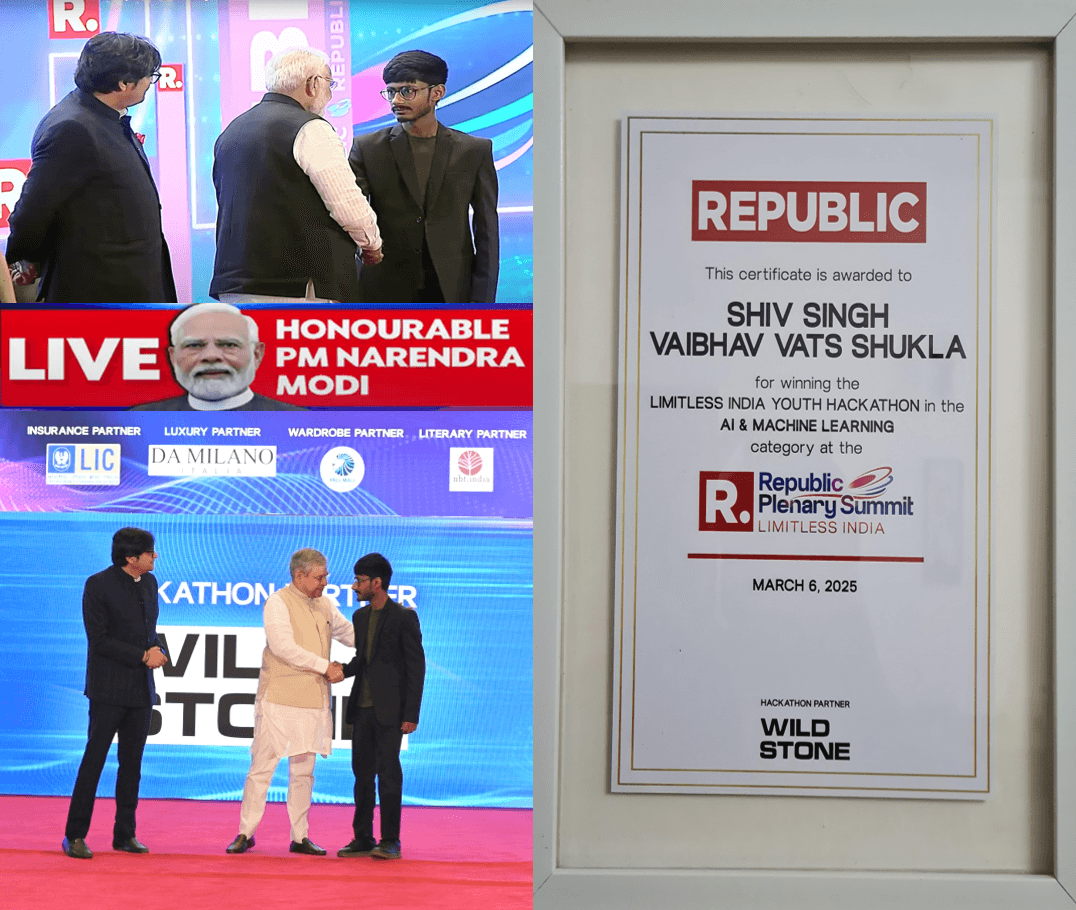
Best Startup in
AI & ML Category
Felicitated by Hon'ble Prime Minister Shri Narendra Modi Ji and IT Minister Shri Ashwini Vaishnaw for building the data foundational layer for India's Sovereign AI mission.
Voice AI today is broken
on every axis.
Cost
A “wrapper tax” on every provider pushes pricing to ₹4 to 22 per minute, with no path down, because you depend on all of them.
Accuracy
Generic STT and TTS fail on regional accents, code-switching and emotional nuance, trained on generic web data, not dialect-rich, emotion-aware data.
Latency
Every vendor hop adds delay. Most cascade setups hit 1 to 2s+, breaking natural conversation flow.
Concurrency & scale
Rate limits and quota caps break the STT, LLM and TTS pipeline at high concurrency. Pre-reserve capacity or lose peak calls.
Data ownership
Every call trains the provider's model, not yours; sensitive data leaves your infrastructure. Your enterprise value is leaking to model providers.
One system.
Every layer.
A single on premises pipeline: the call comes in, speech is detected and transcribed, memory is retrieved, a response is generated and spoken back, all as one unit.
In-house speech models
Finalization under 60ms on STT and latency under 120ms TTFA on TTS, trained on rare dialects, accents and code switching, with voice cloning from a single sample.
Memory & real-time knowledge
Live recall during the call plus full longitudinal customer history, with retrieval under 100ms from enterprise databases so agents act on current business data.
One instance, one unit
Every layer runs together on your infrastructure, so there are no vendor hops, no rate limits and no wrapper tax.
Data that makes
the model better.
High-quality human and semi-synthetic speech across 22 Indian languages, used to fine-tune STT and TTS instead of open-source or distilled data.
Deployed models are fine-tuned monthly on your own call data, inside your infrastructure. The learning never leaves it.
Real Indian voices
at scale
Better models for a
more inclusive AI
More than
a conversation.
Orchestration gives the voice agent realtime tools and a static knowledge base while the call is on. After it ends, the swarm agent writes ERP and CRM updates, insights, and follow-ups into the apps you already use.
ORCHESTRATION
On the call
Voice agent
Both feeds, while it talks
After the call
Swarm agent
ERP and CRM, once it ends




Closed-loop automation
Post-call CRM updates, follow-ups and WhatsApp, email or SMS triggers. Zero human touch.
Telephony engine
Hybrid inbound and outbound on one agent, with smart interruption and idle handling.
Noise-ready
Noise cancellation built for real-world calls, regional accents and code-switching.
Built for scale
No provider rate limits. Concurrency scales with your own infrastructure at peak.
Side by side
Comparison.
| Metric | Quansys AI | Industry |
|---|---|---|
| Voice latency (S2S) | <500ms p99 TTFA | 1 to 2s+ |
| Cost per minute | $0.01 (~₹0.95) | ₹4 to 22 |
| Infra to self-host | <$3.5K/month, including model | — |
| Data ownership | 100% client-owned, on-prem | Leaves client infra |
| Model learning | Trains on your data plus ours | Trains the provider’s model |
| STT Finalization | <60ms | 100 to 350ms |
| TTS TTFA | Sub-120ms | 150 to 500ms |
| LLM TTFT | <250ms | 600 to 1500ms |
Deploy anywhere.
Keep control.
Deployment model
You self-host the full stack on your private infrastructure or a cloud of your choice. Nothing leaves your environment.
How it is licensed
A one-time deployment charge, with your fine-tuned model weight delta licensed for your use, plus recurring licensing and support.
What we are
building next.
Full-duplex speech-to-speech model
One model that listens and speaks in the same turn, so a call can overlap, interrupt, and continue without a cascaded STT, LLM, and TTS pipeline.
Our own inference cloud
Blackwell workstation GPUs dedicated to speech-to-speech inferencing, offered through our unified S2S API.
Own the voice AI stack.
Your data. Your model. Your infrastructure.
A more open tomorrow.